Erik Perry · 8 October 2026
Examining Hash Collision Mitigation Techniques in High-Throughput Distributed Caching Layers
High-throughput distributed caching layers rely on hash functions to map keys to storage slots across multiple nodes, yet collisions arise when distinct keys produce identical hash values and these events create bottlenecks that slow retrieval operations while increasing CPU overhead in systems handling millions of requests per second.
Core Mechanics of Hash Collisions in Distributed Environments
Engineers design hash functions to distribute keys uniformly across available buckets, but in practice certain input patterns cause clustering because real-world workloads often include sequential or patterned data that exposes weaknesses in simpler algorithms such as those based on basic modulo operations. Researchers have documented how these clusters force cache nodes to perform additional lookups or chain entries, and the resulting latency spikes become especially pronounced when throughput exceeds tens of thousands of operations per node.
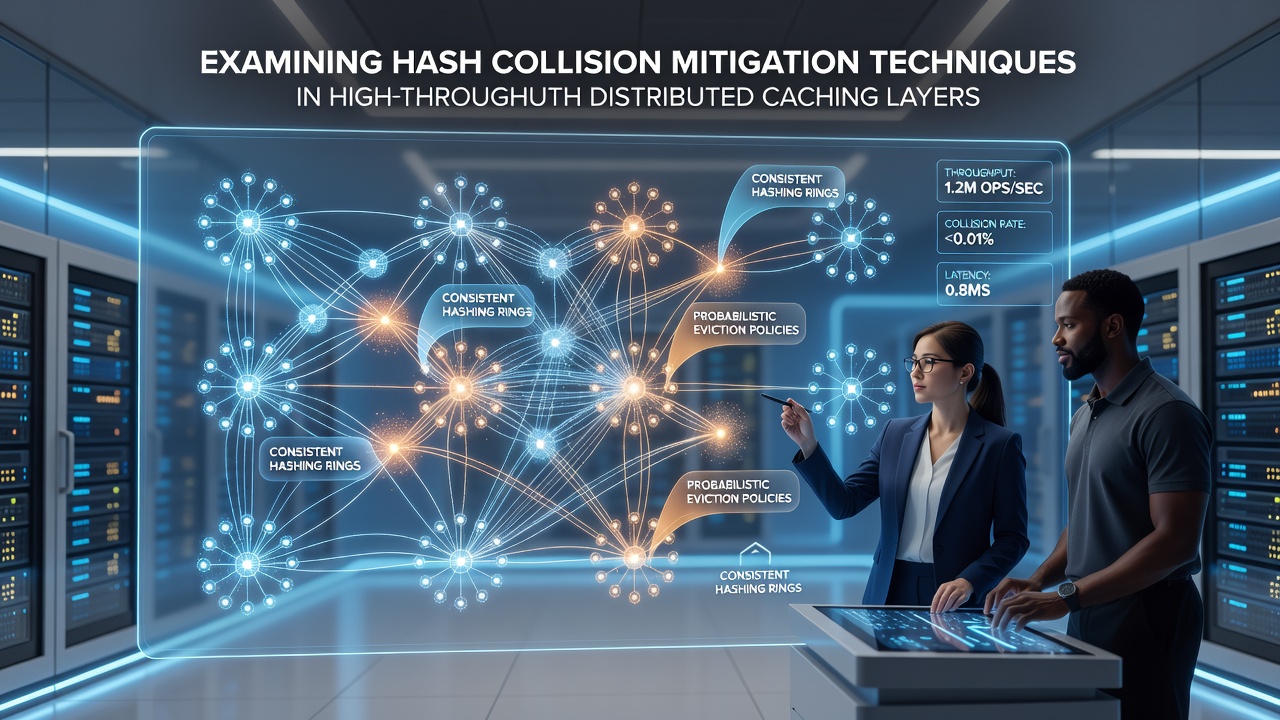
Data from production clusters shows that collision rates climb sharply once cache utilization passes seventy percent, prompting operators to monitor bucket load factors continuously and trigger rehashing procedures before performance degrades noticeably. Consistent hashing variants help limit the scope of rebalancing when nodes join or leave the cluster, yet they do not eliminate collisions entirely and still require secondary resolution strategies at the individual node level.
Primary Mitigation Approaches Deployed Today
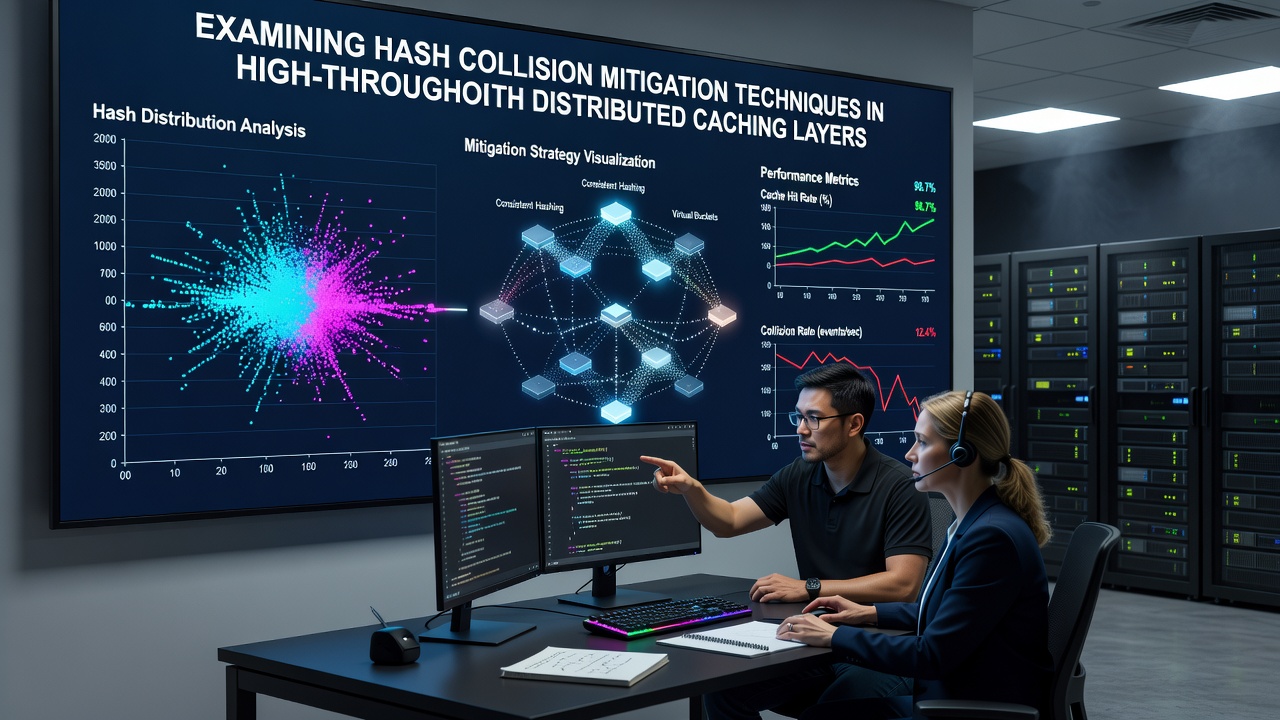
Teams implement stronger cryptographic and non-cryptographic hash functions including variants of MurmurHash3 and xxHash that deliver better avalanche properties and lower collision probabilities under adversarial inputs, and these choices reduce the frequency of conflicts without imposing prohibitive computational costs in read-heavy workloads. When collisions still occur, systems apply open addressing with quadratic probing or separate chaining with linked lists or trees to store multiple entries at the same index, and each method trades off memory usage against lookup speed depending on expected collision frequency.
Cuckoo hashing offers another avenue by maintaining multiple hash tables and allowing items to displace one another until an empty slot appears, and studies indicate this approach maintains constant-time lookups even under higher load factors compared with traditional chaining. Bloom filters sometimes serve as a pre-filter layer that quickly rules out non-existent keys before expensive hash table probes begin, thereby shielding the primary cache structure from unnecessary collision resolution work during negative lookups.
Implementation Patterns Observed in Large-Scale Systems
Operators running global cache fabrics often combine consistent hashing at the distribution layer with per-node cuckoo or chained tables, and this layered strategy confines the impact of any single collision while allowing independent scaling of individual cache shards. In October 2026 telemetry from several hyperscale environments revealed that deployments using hybrid hashing schemes sustained median latencies below two milliseconds even during peak traffic periods exceeding one million requests per second per region.
According to guidelines published by the National Institute of Standards and Technology on hash function selection, organizations gain measurable stability by rotating hash seeds periodically and monitoring statistical distribution metrics across live traffic samples. Academic work originating from institutions in the European Union has further examined how machine-learning models can predict collision-prone key patterns in advance, allowing proactive re-mapping before throughput suffers.
Performance Trade-offs and Measurement Practices
Every mitigation technique introduces measurable costs in either memory footprint, computation time, or implementation complexity, and teams evaluate these factors through controlled benchmarks that simulate realistic key distributions including both uniform random accesses and adversarial sequences designed to trigger worst-case behavior. Metrics such as collision chain length, rehash frequency, and tail latency percentiles guide iterative tuning, while automated tooling now flags anomalies within minutes rather than hours.
Systems that incorporate hardware-accelerated CRC32 or AES-NI instructions for hash computation demonstrate throughput gains of thirty to fifty percent over pure software implementations on modern server CPUs, yet these accelerations require careful validation to ensure the chosen algorithm still provides adequate distribution properties across the full key space.
Conclusion
Hash collision mitigation in high-throughput distributed caching layers continues to evolve through the integration of improved hash functions, refined resolution algorithms, and layered architectural patterns that together maintain performance under demanding workloads. Observers tracking production metrics note steady reductions in collision-related incidents as these combined techniques become standard practice across diverse deployment environments.